SRESchool.com Guide to Site Reliability Engineering Training and Consulting
Introduction
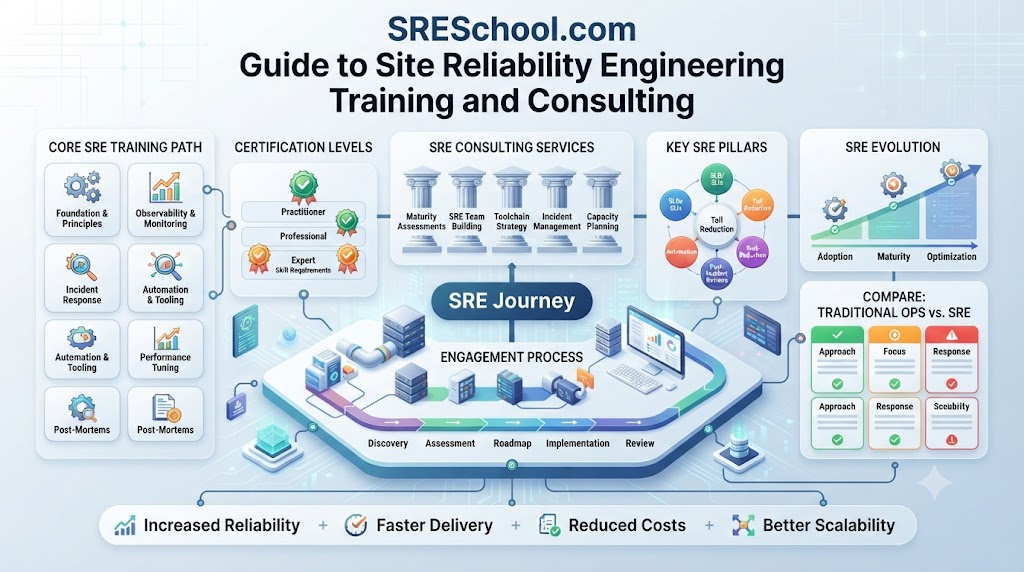
Building reliable, scalable, and resilient digital products remains one of the most demanding challenges modern engineering teams face daily. When production systems fail unexpectedly, user trust drops quickly, and engineers scramble to fix critical system outages under pressure. Site Reliability Engineering introduces disciplined software engineering approaches to infrastructure and operational problem-solving. Platforms like SRESchool.com provide specialized learning resources designed to help engineers master these exact technical disciplines. Whether you want to improve incident response, automate manual work, or understand system observability, structured guidance makes the journey significantly easier. Developing these core competencies ultimately transforms how engineering organizations design, deploy, and maintain cloud infrastructure.
Understanding Site Reliability Engineering and Why It Matters
Site Reliability Engineering originated as a practical way to bridge the traditional gap between software development and IT operations. Traditional operations models often relied heavily on manual server management, leading to chronic engineer burnout and fragile production environments. SRE applies software engineering principles to automate routine operations and build scalable, highly available systems. Instead of reacting blindly to every noisy alert, teams focus on measuring system health, reducing downtime, and implementing automated guardrails. This practice matters because modern users expect web applications and cloud services to function seamlessly around the clock. By prioritizing reliability from the design phase onward, organizations protect their revenue, reputation, and long-term user satisfaction.
What Professionals Can Learn Through SRE Training
Engaging in structured SRE Training helps engineers develop hands-on skills in managing complex, distributed production systems safely. Learners explore core concepts such as service level objectives, error budgets, telemetry collection, and structured incident management. Training programs frequently cover strategies for eliminating toil, which refers to repetitive, manual operational work that lacks enduring engineering value. Engineers also learn how to plan for traffic spikes, design resilient architectures, and troubleshoot complicated cloud environments. These competencies allow technical staff to move away from reactive firefighting and focus on engineering stable, proactive solutions. Acquiring these practical skills benefits software developers, DevOps practitioners, and system administrators alike.
Understanding SRE Certification and Professional Skill Development
Pursuing an SRE Certification gives engineers a structured path to validate their reliability knowledge and professional dedication. Certification requirements, assessment methods, and eligibility criteria vary widely depending on the specific credentialing body chosen. Studying for an exam encourages engineers to dive deep into topics like incident postmortems, SLO design, and observability pipelines. However, earning a certificate does not automatically guarantee employment, promotions, or salary increases in the competitive tech market. Instead, certification serves as a personal milestone that demonstrates foundational knowledge and a commitment to professional growth. Combining certified study with hands-on production experience yields the most meaningful career development.
Choosing a Site Reliability Engineering Course
Selecting a comprehensive Site Reliability Engineering Course requires looking closely at curriculum depth, practical labs, and real-world relevance. A well-designed course should cover both foundational theory and hands-on scenarios like configuring monitoring alerts and writing automation scripts. Learners can reasonably expect to explore how reliability metrics work in microservices and distributed cloud environments. It is helpful to review course outlines to ensure they match your current technical background and career goals. Whether you are transitioning from traditional operations or leveling up your software skills, structured learning accelerates your understanding. Choosing the right course helps you apply reliability patterns directly to your daily engineering work.
What It Means to Become a Certified Site Reliability Engineer
Becoming a Certified Site Reliability Engineer represents a milestone in mastering production engineering and system stability. A certified professional typically demonstrates deep understanding of how to measure uptime, manage incidents, and automate repetitive workflows. They know how to balance feature delivery speed with system resilience using data-driven error budgets. This role requires strong collaboration skills, as engineers work closely with software developers to improve code maintainability and observability. Being certified reflects a dedication to rigorous engineering practices rather than just fixing broken servers. It signals to peers and organizations that an engineer values proactive reliability over reactive patching.
| Focus Area | Core Competency | Practical Application |
|---|---|---|
| Observability | Metrics, logs, and traces | Understanding live system behavior |
| Reliability | SLOs and error budgets | Balancing feature releases with stability |
| Operations | Incident management | Resolving production outages efficiently |
| Automation | Toil reduction | Eliminating manual, repetitive tasks |
Exploring SRE Consulting for Organizations
Organizations often reach a point where internal teams need external guidance to scale their infrastructure reliability effectively. SRE Consulting helps businesses assess their current reliability maturity, identify operational bottlenecks, and design robust architectures. Consultants evaluate existing monitoring setups, incident response workflows, and deployment pipelines to recommend targeted improvements. This external perspective helps leadership teams uncover hidden technical debt and architectural risks before they cause major outages. By partnering with experienced practitioners, companies can adopt industry best practices faster and avoid costly trial-and-error mistakes. Tailored consulting ensures that reliability strategies fit the specific business goals and technology stack of the organization.
Understanding SRE as a Service
SRE as a Service provides organizations with ongoing external reliability expertise for their cloud infrastructure and production platforms. Rather than building a large internal reliability team from scratch, smaller companies can leverage outsourced specialized support. This model typically includes monitoring assistance, incident triage, automation development, and continuous reliability reviews. While not every organization requires outsourced support, it offers a flexible way to bridge skill gaps during rapid growth phases. SRE as a Service helps maintain high service availability while internal engineers focus on core product development. It acts as an extension of your engineering department when specialized reliability bandwidth is needed.
Why Corporate SRE Training Can Help Engineering Teams
Implementing reliability practices across an entire enterprise requires shared understanding and common vocabulary among all technical teams. Corporate SRE Training helps align software developers, DevOps engineers, and operations staff around common reliability goals. Structured training programs can be tailored to match the company’s specific working environments, cloud providers, and technology stacks. When teams train together, they build a collaborative culture that treats reliability as a shared responsibility rather than an afterthought. This collective knowledge reduces friction between development and operations departments, leading to faster and safer deployments. Investing in corporate training builds long-term technical resilience from the ground up.
Learning Through Practical SRE Tutorials
Engaging with targeted SRE Tutorials offers learners an accessible way to grasp complex engineering concepts step by step. Tutorials often guide readers through practical tasks, such as configuring a basic monitoring dashboard or calculating an error budget. These hands-on guides help bridge the gap between abstract theoretical principles and real-world implementation. Learners can experiment with configuration files, log aggregators, and synthetic testing tools in safe sandbox environments. Exploring diverse tutorials allows engineers to build confidence before applying changes to production systems. Consistent practice through guided tutorials reinforces problem-solving skills essential for modern infrastructure engineers.
Exploring SRE Tools for Modern Reliability Engineering
Selecting the right technology stack is vital for maintaining visibility and control over distributed production environments. SRE Tools span several categories, each serving a distinct purpose in the reliability lifecycle.
- Monitoring and Metrics: Tools that collect numerical time-series data to track CPU, memory, and request rates.
- Logging: Systems designed to ingest, index, and query application and system log streams.
- Distributed Tracing: Technologies that track request paths across microservices architectures to identify latency bottlenecks.
- Incident Management: Platforms that handle on-call paging, alert routing, and collaboration during outages.
- Infrastructure Automation: Software used to provision and configure cloud resources consistently using code.
No single tool is universally the best for every organization; selection depends on scale, architecture, and team familiarity.
Understanding SLOs, SLIs, and Error Budgets
Service Level Indicators, or SLIs, measure aspects of service performance, such as request latency or error rates. Service Level Objectives, or SLOs, set the target reliability level for those indicators over a specific time window. Error budgets represent the acceptable amount of unreliability a service can experience before developers must pause new feature releases. This framework transforms vague discussions about quality into measurable, data-driven conversations between product and engineering teams. When the error budget is healthy, teams can ship new features quickly; when it depletes, focus shifts to reliability work. This balanced approach aligns engineering speed with user expectations.
How Observability Supports Site Reliability Engineering
Observability allows engineering teams to infer the internal state of a system based on its external outputs. Unlike traditional monitoring, which tells you when a system is broken, observability helps you understand why it broke. By combining metrics, logs, and distributed traces into unified dashboards, teams gain deep visibility into complex microservices. When an anomaly occurs, engineers can query telemetry data to trace the root cause across multiple dependent services. Good observability practices drastically reduce mean time to resolution during critical production incidents. Cultivating strong observability habits is a cornerstone of effective production engineering.
Understanding Incident Management and Postmortems
Production incidents are inevitable in complex software systems, making structured incident management a critical operational capability. Effective incident processes involve rapid detection, clear on-call paging, cross-team triage, and structured communication. Once the immediate crisis is resolved, conducting a blameless postmortem helps teams analyze what went wrong and why. Postmortems focus on systemic and procedural factors rather than pointing fingers at individual engineers. Documenting lessons learned and creating actionable follow-up tickets prevents the same failure from happening again. This continuous learning loop strengthens system resilience over time.
How Automation and Toil Reduction Improve Reliability
Manual operational tasks slow down deployment velocity and increase the likelihood of human error during routine updates. Automation allows SRE teams to replace repetitive operational work with reliable scripts, pipelines, and self-healing systems. Reducing toil frees up engineering hours for high-value projects like architecture improvements and feature development. However, poorly designed automation can introduce new risks if scripts fail silently or lack proper monitoring. Therefore, automation code must be tested, reviewed, and maintained with the same rigor as application software. Balancing automation with thoughtful oversight creates a stable and efficient operational environment.
Understanding Capacity Planning and Cloud Reliability
Anticipating future resource needs ensures that applications continue performing smoothly during unexpected traffic surges. Capacity planning involves analyzing historical usage trends, performance metrics, and upcoming business events to forecast infrastructure requirements. Cloud reliability practices ensure that resources can scale dynamically without blowing budgets or causing service degradation. SRE teams evaluate resource utilization limits, network bandwidth, and database scaling thresholds regularly. Proactive capacity management prevents sudden outages caused by resource exhaustion during peak usage windows. Aligning technical capacity with business growth is essential for maintaining dependable cloud services.
Building a Practical SRE Implementation Approach
Adopting reliability engineering practices requires a gradual, deliberate strategy tailored to an organization’s maturity level. Trying to implement every advanced SRE concept at once often leads to organizational fatigue and resistance.
- Assess Current State: Evaluate existing monitoring gaps, incident response workflows, and team workloads.
- Define Initial Metrics: Start by establishing basic SLIs and SLOs for your most critical user-facing services.
- Improve Observability: Ensure teams have reliable access to logs, metrics, and traces during incidents.
- Automate Repetitive Tasks: Identify high-toil operational chores and build simple automation scripts to handle them.
- Iterate and Refine: Review postmortems regularly and adjust reliability targets based on real-world feedback.
A phased adoption model ensures sustainable cultural and technical progress.
How SRESchool.com Supports SRE Learning and Professional Development
Mastering reliability engineering requires access to structured, high-quality educational resources and practical guidance. SRESchool.com provides a dedicated learning platform where engineers and organizations can explore SRE Training, certification pathways, and curated tutorials. Whether you are studying foundational SLO concepts or evaluating modern SRE Tools, the platform supports continuous professional growth. Its comprehensive resources help bridge the knowledge gap for DevOps engineers, platform architects, and operations professionals alike. By centralizing learning materials, the platform makes it easier for technical practitioners to build robust reliability skills. Exploring these resources empowers engineers to design more resilient and scalable production systems.
Why Reliable SRE Knowledge Is Becoming More Important
As digital infrastructure grows increasingly distributed and complex, system failures carry higher operational and financial costs. Organizations can no longer rely on guesswork or ad-hoc troubleshooting when managing cloud-native production platforms. Reliable SRE knowledge provides a proven framework for maintaining uptime, managing risk, and scaling engineering operations. Professionals who understand observability, automation, and error budgeting are in high demand across the technology sector. Prioritizing continuous learning in reliability practices protects both organizational reputation and customer trust. Building this expertise is a strategic investment in the future of any technology-driven business.
Frequently Asked Questions About SRESchool.com
What is SRESchool.com?
SRESchool.com is a specialized global learning and professional services platform dedicated to Site Reliability Engineering, helping engineers and organizations build reliable, scalable, and resilient production systems.
What topics are covered in SRE training programs?
Training programs typically cover practical skills in SLOs, SLIs, error budgets, observability, incident management, automation, capacity planning, cloud reliability, and toil reduction.
Does SRESchool.com offer professional certification paths?
The platform supports professional development by helping engineers navigate learning paths relevant to reliability engineering, incident response, and production operations.
Who can benefit from a site reliability engineering course?
DevOps engineers, cloud engineers, platform engineers, software engineers, and operations professionals can all benefit from understanding how SRE principles apply to real production environments.
What does it mean to be a certified site reliability engineer?
It reflects a validated understanding of reliability measurement, monitoring, incident response, postmortems, automation, and production engineering best practices.
How does SRE consulting help organizations?
Organizations use consulting support to assess reliability maturity, establish SLO strategies, improve observability, strengthen incident management, and reduce operational toil.
What is SRE as a Service?
SRE as a Service provides businesses with ongoing external reliability expertise and support for their cloud infrastructure and production platforms.
How does corporate SRE training work for teams?
Corporate training helps engineering teams build unified reliability knowledge tailored to their specific working environments, architectures, and technology stacks.
What tools are typically explored in SRE tutorials?
Tutorials cover technologies used for monitoring, observability, automation, infrastructure management, incident response, and cloud-native operations.
Is SRE experience required before starting?
While basic programming and system administration knowledge helps, learning resources are structured to accommodate professionals at various stages of their engineering careers.
Final Thoughts
Site Reliability Engineering transforms how technical teams approach uptime, system stability, and operational workload. By shifting from reactive firefighting to proactive measurement and automation, organizations build products that users can trust. Platforms like SRESchool.com provide the structured learning and guidance necessary to navigate this journey successfully. Whether you are an individual engineer pursuing skill development or an enterprise team refining cloud operations, continuous improvement is key. Embrace reliability not as a set of rigid rules, but as an engineering mindset focused on sustainable growth and resilience.
Leave a Reply